

Accelerate Spark Without the Migration
Boost processing performance for faster job completion.
Shrink clusters and cut resource costs.
Plug Flarion into AWS EMR, Azure HDInsight, GCP Dataproc, Databricks and On-Prem.
Spark vs. Flarion-Powered Spark
Core Capabilities
Upgrade Spark’s engine for unmatched speed and efficiency.
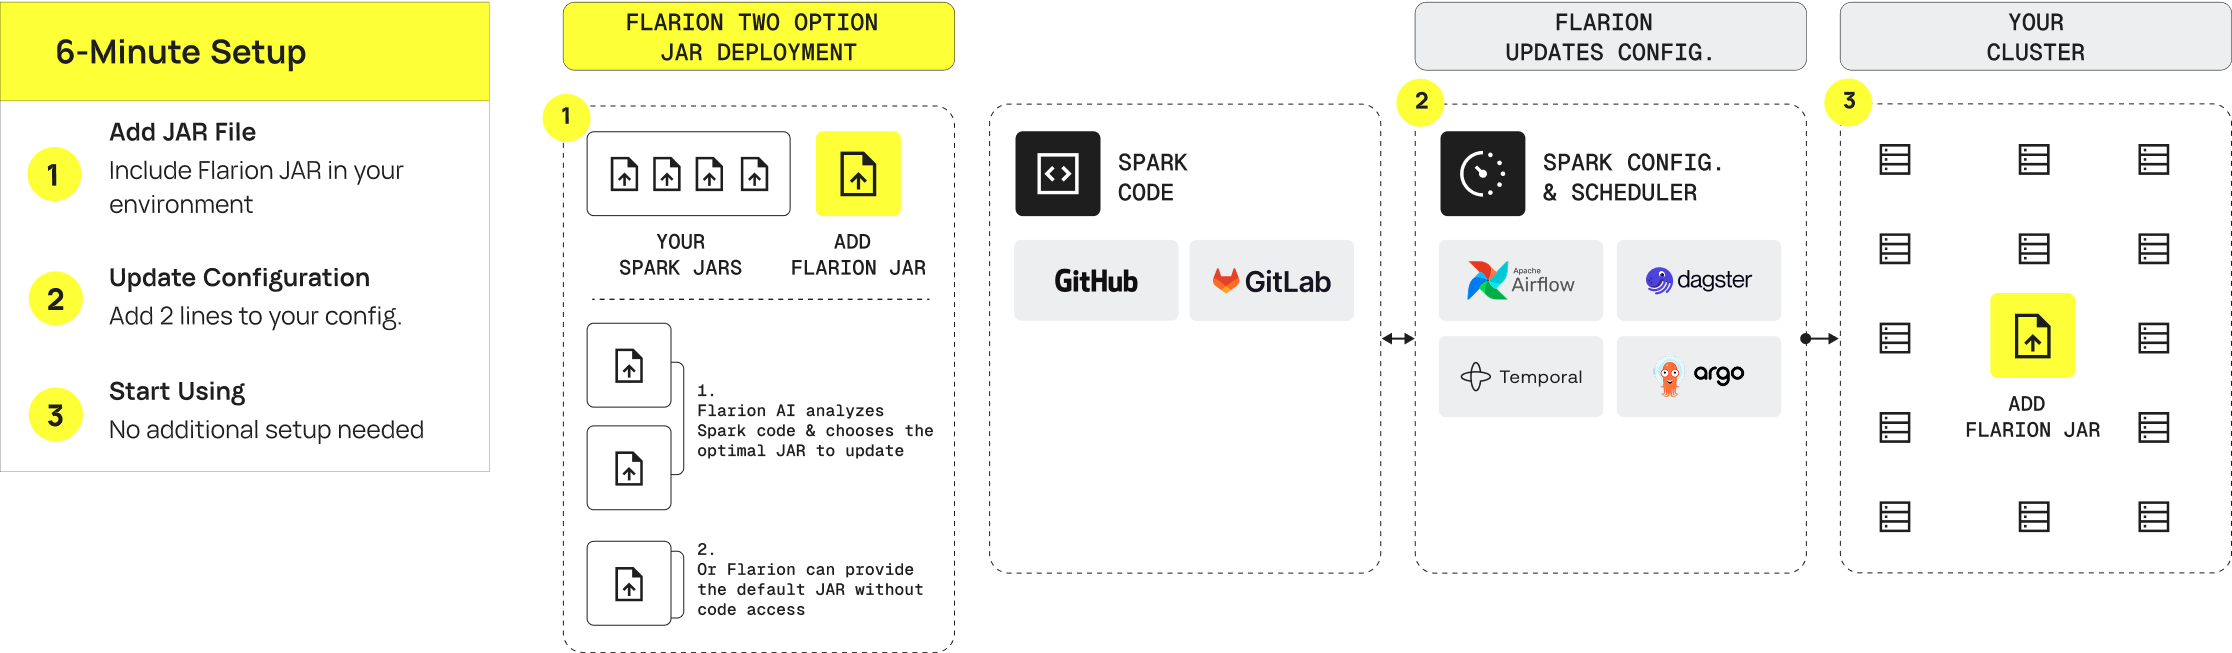
Flarion installs as a Spark Extension, with no workflow changes required. Just drop in a JAR file, add two config lines, and go.
Flarion runs agentlessly within your environment, it has no access to your business data and requires no permissions.
Whether you're running on Databricks, EMR, or Kubernetes, Flarion delivers predictable performance improvements without tuning or customization.
Validated through the official Spark test suite to ensure seamless compatibility with your existing jobs and queries.

How Flarion’s Accelerator Works
Standard Spark distributes tasks across machines but is constrained by the inefficiencies of Java execution, leading to:
- Higher Resource Usage
- Slower Processing
- Limited Optimization

Flarion-Powered Spark replaces Spark Java execution engine with Flarion's DataFusion and Arrow-based engine for acceleration of Operators and expressions like filter, groupBy, and join, no code changes needed.

Spark divides jobs into smaller tasks across multiple machines, but its Java-based execution engine limits performance on complex computations.
Flarion replaces Java execution with our DataFusion and Arrow-powered engine, compiling SQL queries into optimized Rust code to accelerate CPU-bound tasks like filter, groupBy, and join, no code changes, no disruptions.
Seamless Engine Replacement for Powerful Spark Execution
Flarion Accelerator integrates with Spark by replacing the default physical plan with an enhanced version that directs execution to our high-performance engine. At the same time, Spark continues to manage orchestration—delivering faster and more efficient processing.

Plug & Play in Seconds
.config("spark.sql.extensions",
"flarion.extensions.DataEngine")
.config(“flarion_user_id”, “12345”)
Integration Across
All Platforms

Deploy via Init Scripts for runtime optimization.
Deployed as a bootstrap action.
Configured with initialization actions.
Integrated via script actions for enhanced performance.
Deploy with Helm charts or Spark operator modifications; Kubernetes handles scaling while Flarion optimizes in real-time.
Install on Spark nodes using tools like Ansible or Chef, optimizing SQL operations.
3x Faster Processing And 60% Cost Savings
Minimal Effort
No code changes or tuning needed for immediate performance boosts.
Stability
Smaller, more stable clusters reduce node failures for resilient operations.
Resource Usage
Lower infrastructure demands, enabling efficient data processing.
Assess Before You Accelerate
This zero-effort assessment helps you:
The Latest Data Processing News & Insights

